The scenario is uncomfortable because it needs no attacker.
A nightly workflow has been running cleanly for months: approved, signed, scheduled at 02:00. Then something underneath it changes — an admin revises a capability it depends on, a new version of a data surface ships, or the database schema itself moves. No ticket touches the workflow. The next unattended run now reflects a data surface no human re-reviewed for this workflow.
Every automation platform has this exposure. Most answers are procedural ("don't do that") or retrospective (an alert after the run, when the report already went out). Kavros answers with two mechanisms that have deliberately different teeth — and because a governance vendor's claims should survive contact with its own product, this post describes both as they actually behave in release 0.2.15, verified during our launch rehearsal. One of our own earlier sentences about this was too strong; we fixed the sentence, not the test.
What "drift" means here
Drift is any divergence between what an approved workflow's revision pinned and what the world now resolves to. It arrives at two layers:
- The capability layer moves. A workflow revision pins capabilities at specific versions with specific approved fields. When an admin publishes a new capability version, the pinned reference no longer matches current reality.
- The ground under the capability moves. The workflow and the capability are both untouched — but the underlying database object changes: a table is renamed or dropped, a column vanishes, a schema loses approval. The approved definition no longer describes something that exists.
Different layers, different mechanisms. One is a governance flag; the other is a hard stop.
Tier 1 — capability changes: flagged, and runs continue
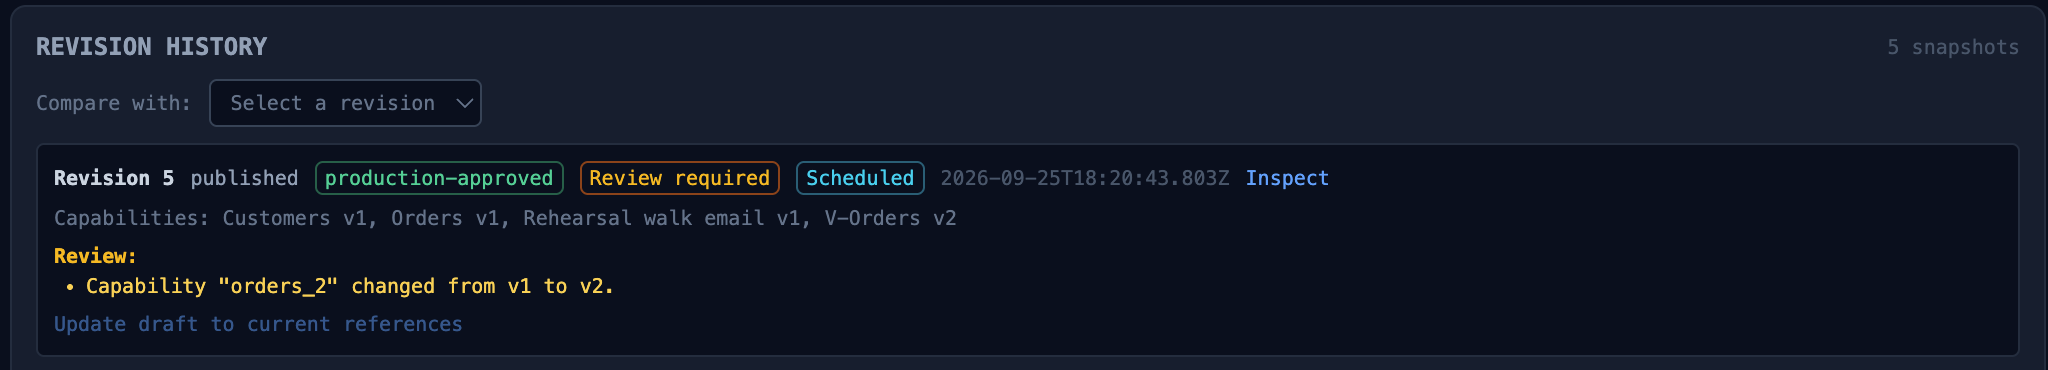
When a capability a published revision depends on changes version or source, the workflow does not halt. Here is the review line, verbatim from a rehearsal deployment where we revised a capability from v1 to v2 under a production-approved workflow (revision panel, condensed):
Capability "orders_2" changed from v1 to v2.
The change is flagged for review, and the flags attach where decisions get made:
- The revision panel lists the exact divergence — which capability, from which version to which.
- The workflow list shows the drift badge ("needs review — capability drift detected").
- Publishing a new revision through the drift requires an explicit review confirmation — the gate asks, and records the answer.
- Enabling or re-checking a schedule over a drifted revision hits the same review gate.
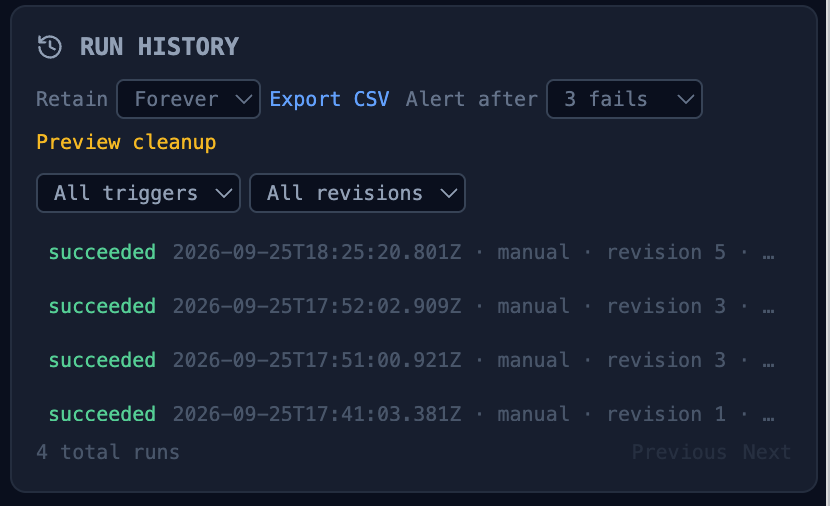
Meanwhile, runs continue under the signed revision. That is a deliberate design, not an oversight: the revision is what a human approved, its signature is what the evidence chain cites, and an unattended schedule dying overnight because an admin published v2 of an unrelated capability would make governance the availability problem. The flag's job is to put a human decision back in the loop before the system re-blesses anything — the workflow cannot silently adopt v2, and it cannot approve the change itself.
The honest edge: run-time enforcement reads the capability's current approved fields, while the evidence labels the pinned version. So if a change widens the approved surface, the review flag — not a run gate — is what stands between the wider surface and the schedule until a human acts. We say that plainly because we first wrote this paragraph without it. Treating drift flags as real work is part of operating the product; making runs refuse when effective scope exceeds the pinned scope is on our own hardening list.
Tier 2 — source schema drift: suspended, refused before any query
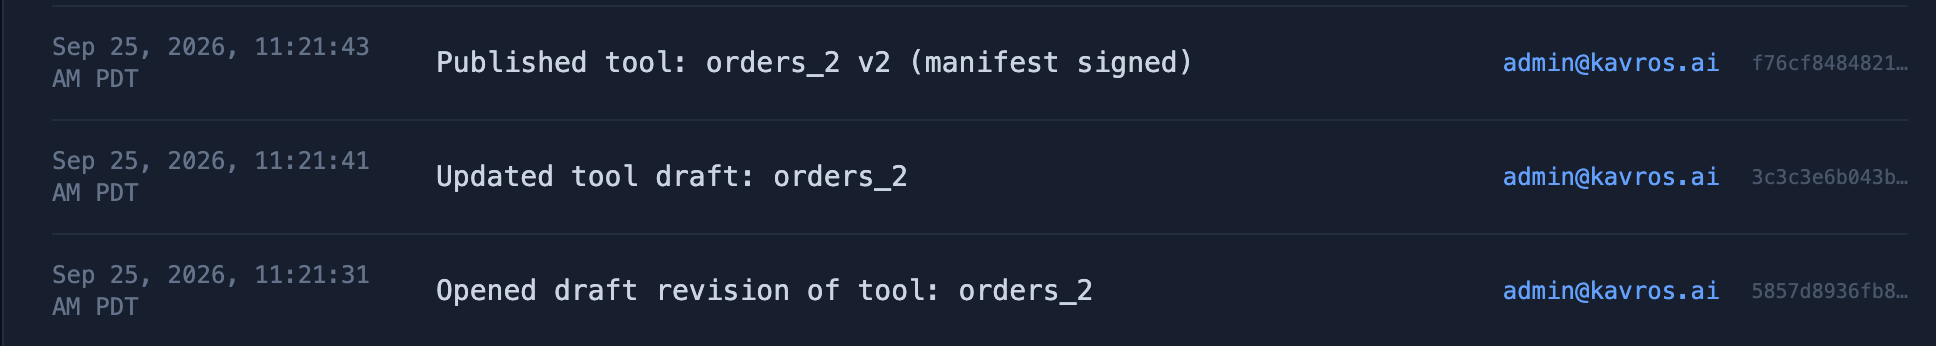
The second layer is harder, and so is the response. When the underlying source of a published capability no longer matches its approved definition — object gone, columns changed, schema unapproved, connection failing — the scheduled drift check (every 15 minutes, alongside schedule claims) re-derives the live source facts and compares them to the approval. On mismatch, the capability is auto-suspended: the shared execution core refuses every call — workflow, MCP, editor test — from that moment:
Tool "orders" is suspended pending re-approval (source schema drift)
A critical incident opens in the Task Inbox with the reason attached. The next scheduled run doesn't partially execute, and it doesn't guess: the refusal happens before the database is touched. Recovery is ordinary governance — the source is fixed or the capability is re-published against reality, the next clean check clears the suspension, and the incident resolves. The whole episode — drift, suspension, refusal, decision, recovery — lands in the hash-chained trail.
The invariant, precisely stated
The property the architecture guarantees is: a workflow cannot grant itself scope. Graph changes enter only through the draft → approval → signed-revision lifecycle. Capability changes surface as review flags at the publish and schedule gates — a human confirms, on the record. Source-level breakage suspends the capability outright. What the system does not do is auto-halt every run under a version-drifted revision — that trade-off buys availability and evidence stability under the signed baseline, and we think it's the right call. If you disagree, that's a legitimate architecture conversation to have with us before you buy, not after.
What this does not claim
- Flagged ≠ halted. Version and source changes under an approved revision are flagged; runs continue under the signed revision until a human re-approves. Only source schema drift produces the hard pre-query refusal.
- Scope-level, not semantic. Drift detection catches changes to what the workflow can touch. It does not judge whether an in-scope workflow is useful or its prompt is well-written.
- The allowlist is a ceiling. A workflow authorized to read customer names can still mishandle customer names inside that boundary. Governance bounds behavior; it doesn't certify intent.
- Drift detection is not intrusion detection. It catches unauthorized change against an approved baseline. Compromise of the approval path itself is a different threat model, answered by the audit trail's hash chain — tampering with history is detectable after the fact, by design.
Run it yourself
The sandbox's workflows track simulates the drift case, beside the real product video of a governed run. And if you want to see both tiers against your own workflow's shape — its data, its capabilities, its revision history — that's the 20-minute architecture assessment.
Missed part 1? From plain English to a signed, scheduled run covers how a workflow gets approved and scheduled in the first place.